IT automation for fewer interruptions
When a new employee waits two days to access systems, an invoice is manually processed in multiple places, or a critical notification goes unnoticed, the problem is not just in a single task. It is a process that depends on people’s memory, availability, and attention. IT automation removes this dependency where it brings unnecessary risk, delay, and unforeseen costs.
For small and medium-sized companies, automation doesn’t necessarily mean a big project, a new complex platform, or replacing teams. In practice, it means clearly defined rules: what happens when a certain event occurs, who gets notified, how a request is created, when access is restricted, and how the result is verified. Well-chosen automations free up time for higher-value work and reduce the likelihood that a small missed step will turn into an operational problem.
Where IT automation has the fastest impact
The most useful automation starts with repetitive activities with a clear result. If a task is performed dozens of times a month, follows the same rules, and a mistake in it leads to delay or risk, it is a good candidate. The goal is not to automate every action, but to make the routine controlled and traceable.
User and Access Management
Employee onboarding, moving, and terminating often involve multiple systems: email, cloud platforms, shared folders, business applications, VPNs, and telephony. When these steps are performed manually and without a common process, two typical problems arise. New people don’t get the necessary rights in a timely manner, and those who have left can retain access longer than necessary.
An automated workflow can create a request when an employee joins, assign pre-approved roles, notify responsible individuals, and document each step. Upon termination, the same approach deactivates accounts on a set schedule, transfers work information, and leaves an auditable trail. This is both a productivity improvement and a significant control for information security.
Helpdesk and request processing
Some of the requests to IT support are predictable: a forgotten password, a request for access, the installation of approved software, or a report of a device problem. Automation can categorize requests, route them to the right team, send instructions for common cases, and escalate a ticket that has not been processed within the agreed time frame.
This does not eliminate the need for specialists. On the contrary, it allows them to devote attention to incidents that require analysis and competent intervention. For the business, the result is more predictable response times, better accountability, and fewer cases in which the user does not know who is working on their problem.
Infrastructure monitoring
Servers, network equipment, backups, and key cloud services must be monitored constantly, not just when someone reports a problem. Automated monitoring tracks metrics such as free disk space, load, service availability, failed login attempts, and archive status. In case of deviation, the system creates an incident, notifies the responsible persons and, when safe, performs a pre-approved action.
For example, when a system disk is full, an alert can be sent early enough, instead of a critical service being stopped during business hours. If a backup fails, an automatic notification turns the problem into a visible task, rather than an unpleasant surprise when recovery is needed. This is also how we monitor our clients' servers - see server support for businesses.
Security and compliance
Automation also plays an important role in enforcing security policies. It can check whether devices have up-to-date protections, whether encryption is enabled, whether there are risky administrator rights or whether a user is trying to log in from an unusual location. Depending on the scenario, the system can ask for additional confirmation, limit a session or send a signal for investigation.
Here, balance is crucial. Too strict rules can slow down legitimate work, while too loose ones leave gaps. For GDPR, ISO 27001 or NIS2 requirements, automation helps ensure controls are consistently applied and there is evidence of actions taken. However, it is not a substitute for policies, risk assessments and responsible people reviewing exceptions.
How to choose the right processes to automate
The most common mistake is to start with the technology. First, you need to look at how the process currently works. If approvals are unclear, data is incomplete or different people are following different rules, automation will only accelerate the chaos.
A useful starting question is: what repetitive task is most likely to slow down employees, lead to errors or require manual review? Then you need to measure the volume. A process that takes five minutes but happens a hundred times a month can have a greater impact than a single complex task that is performed once a year.
Also assess the consequences of an error. Automating user profile creation can save time. Automating deactivation of access upon exit can both save time and reduce serious risk. It is the processes with high frequency and high cost of error that usually deserve priority.
Before implementation, it is necessary to specify the owner of the process, the conditions for starting, the required data, approvals and the cases in which the automation should stop and hand over the task to a human. This preparation makes the solution manageable and prevents situations in which a system performs a technically correct action with a business incorrect result.
Why control is more important than the number of automations
Successful IT automation is not measured by the number of scripts, integrations or tools used. It is measured by fewer interruptions, faster processing, lower risk and a clear ability to track what has been done. To do this, every automation must have an owner, documentation, an action log and a change procedure.
Automations with access rights, data deletion, configuration changes, and security system actions require special attention. They should operate with the minimum necessary permissions, be tested outside of production whenever possible, and have a clear rollback mechanism. An automated action is only useful if the organization can explain why it was performed and how it would respond in the event of an unexpected result.
Periodic review is also necessary. Businesses change: new roles are assigned, applications are introduced, regulatory requirements change. A rule that was correct a year ago may now grant too broad permissions or create unnecessary requests. Regular review keeps automation useful, not just running on inertia.
The most common causes of outages are not random
In many companies, the IT environment seems stable until a few old problems accumulate. A workstation has not been replaced for years. A switch operates without a backup power supply. Antivirus protection varies on individual machines. Cloud accounts are administered by multiple people, without clear rules. These weaknesses rarely lead to an incident immediately, but they increase the likelihood of an outage.
Common sources of problems are the lack of standardization, the absence of preventive maintenance and the reactive work model. If IT support comes into play only when something has already stopped, the organization is constantly working after the problem, not before it. This means longer outages, more difficult diagnostics and more expensive recovery.
There is a separate issue with security. Some of the most serious outages today are not hardware-related, but the result of cryptoviruses, compromised accounts, or human error in access and permissions. If the environment is not protected and monitored, an outage can start as an incident and grow into a crisis.
Redundancy where downtime costs the most
Not every company needs an expensive architecture with full high availability. But almost every company needs redundancy in at least a few critical points. Most often, these are internet connectivity, archiving, power supply, and access to key systems.
For example, a second Internet provider makes sense if a connection outage blocks sales, service, or the work of distributed teams. UPS protection is mandatory when a sudden outage could damage equipment or interrupt important services. Backup is only valuable if it can actually be restored and this is verified. Many organizations realize too late that they have an archive but no working recovery.
The trade-off here is financial. Redundancy costs money, but not having it often costs more at the most inopportune moment. The sensible approach is to calculate the cost of an hour of downtime and plan your protective measures accordingly.
Standardization is an underrated tool
When a company has different versions of operating systems, inconsistent settings, randomly selected software, and devices with unknown histories, support becomes slow and risky. In the event of an incident, each machine is a separate case. This prolongs both diagnostics and recovery.
Standardization does not mean unnecessary bureaucracy. It means a predictable environment. Uniform update policies, clear access levels, approved applications, centralized device management, and documented configuration. The more uniform and controllable the environment, the fewer unknowns there are in the event of a problem.
This is especially important for growing organizations. When hiring people quickly and opening new offices, chaos builds up imperceptibly. Without a standard, each new user and each new device increases the risk of an outage.
How to reduce IT outages through change control
Many incidents do not come from accidents, but from hasty changes. An update made during business hours. A change to a network setting without testing. New cloud access granted without checking rights. When change is not planned and documented, even a small oversight can bring an entire team to a standstill.
That’s why change control is a practical, not a formal process. It’s important to know what’s changing, when, what the risk is, who approves, and what the plan is for rolling back in case of a problem. Not every change requires a heavy-handed procedure, but every change to a critical system should have an owner and a clear window for implementation.
This is one area where discipline pays off. Fewer surprises, fewer downtimes, shorter response times when something does go wrong.
The post-incident process is just as important
Reducing disruptions does not end with a quick fix for the problem. If there is no analysis of why it happened and how to prevent it from happening again, the organization remains vulnerable. It is good practice to have a brief review of the cause, response time, affected systems and corrective actions after every major incident.
In this way, organizational knowledge is gradually accumulated. It is visible which problems are recurring, which suppliers or components are risky and where capacity is lacking. This allows the IT budget to be directed more wisely - towards prevention with a measurable effect, rather than chaotic purchases under pressure.
For many companies, the best result comes when they have a single point of contact, proactive monitoring and clear responsibility for the environment. It is this model of work that reduces dependence on individual people and turns IT support into a controllable process, rather than a series of emergency reactions. This is the reason why companies look for a partner like Helpdesk Bulgaria not only for troubleshooting, but for stability, accountability and predictable work.
If you are looking for how to limit interruptions, start not with the loudest problem, but with the most critical for the business. There the effect is visible the fastest, and a good IT environment is built exactly like this - with clear priorities, consistency and control.
Practical approach to implementation
A smart start is with a limited process that has a visible problem and a measurable result. For example, automatically creating and routing helpdesk requests, verifying successful archiving, or a standardized process for onboarding a new employee. Establish a baseline: how long the task currently takes, how many errors there are, and how often rework is required.
After implementation, monitor not only the technical performance but also the actual user experience. If automation reduces processing time but creates ambiguity about who approves requests, the process needs to be adjusted. Small improvements, tested in a real environment, build trust and provide a basis for the next steps.
In more complex environments, an external IT partner can connect automation with proactive monitoring, helpdesk processes, device management, and security policies. This way, solutions are not isolated technical initiatives, but are aligned around business continuity and specific company goals.
The best first step is not to automate everything. Choose one task that currently takes time, creates risk, or interrupts people’s work, and turn it into a clear, measurable, and controlled process.
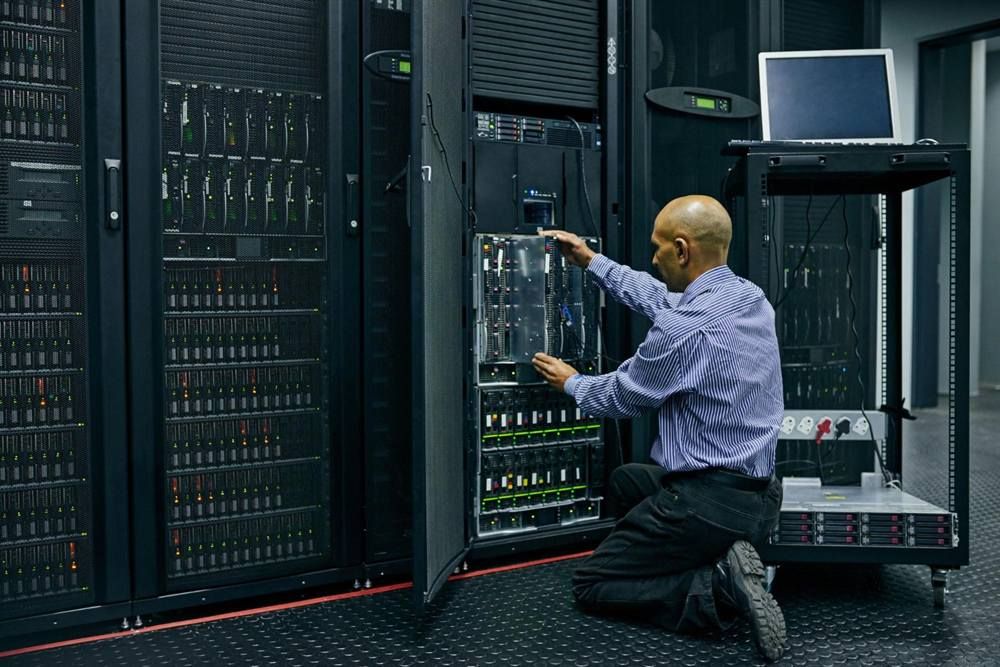
A real-world example: automated patch management in a large server environment.
Let's talk about your company's IT needs: we will review where time is lost and what can be automated and suggest the best solution and price. See computer and IT support for businesses or let's talk about your needs directly.
Tags:
Thank you! We will get back to you within 1 business day.
Something went wrong while sending. Please try again.